Duration
8.0 hr(s) · 1 Day Intensive
Data engineering looks familiar from the outside - it's code, storage and pipelines - right up until a backfill silently doubles a table, or a schema change three systems upstream breaks a dashboard nobody knew depended on it. This course is about the parts that don't transfer from application development.
In a single hands-on day you'll build a working data lake on Databricks with Delta Lake, moving data through bronze, silver and gold layers. The discipline you already have - version control, testing, modular code - is an advantage here, and you'll apply it directly to pipelines. No prior data engineering experience is assumed.
Explain why data lakes exist, where warehouses still win, and what keeps a lake from becoming a swamp.
Build Delta tables with ACID writes and schema enforcement, and recover from bad writes with time travel.
Move data through bronze, silver and gold layers with idempotent, re-runnable transformations.
Apply version control, configuration and testing to pipelines, and recognise the failure modes that bite first.
Upon meeting at least 75% attendance and passing the assessment(s), participants will receive a Certificate of Completion from Zenika.
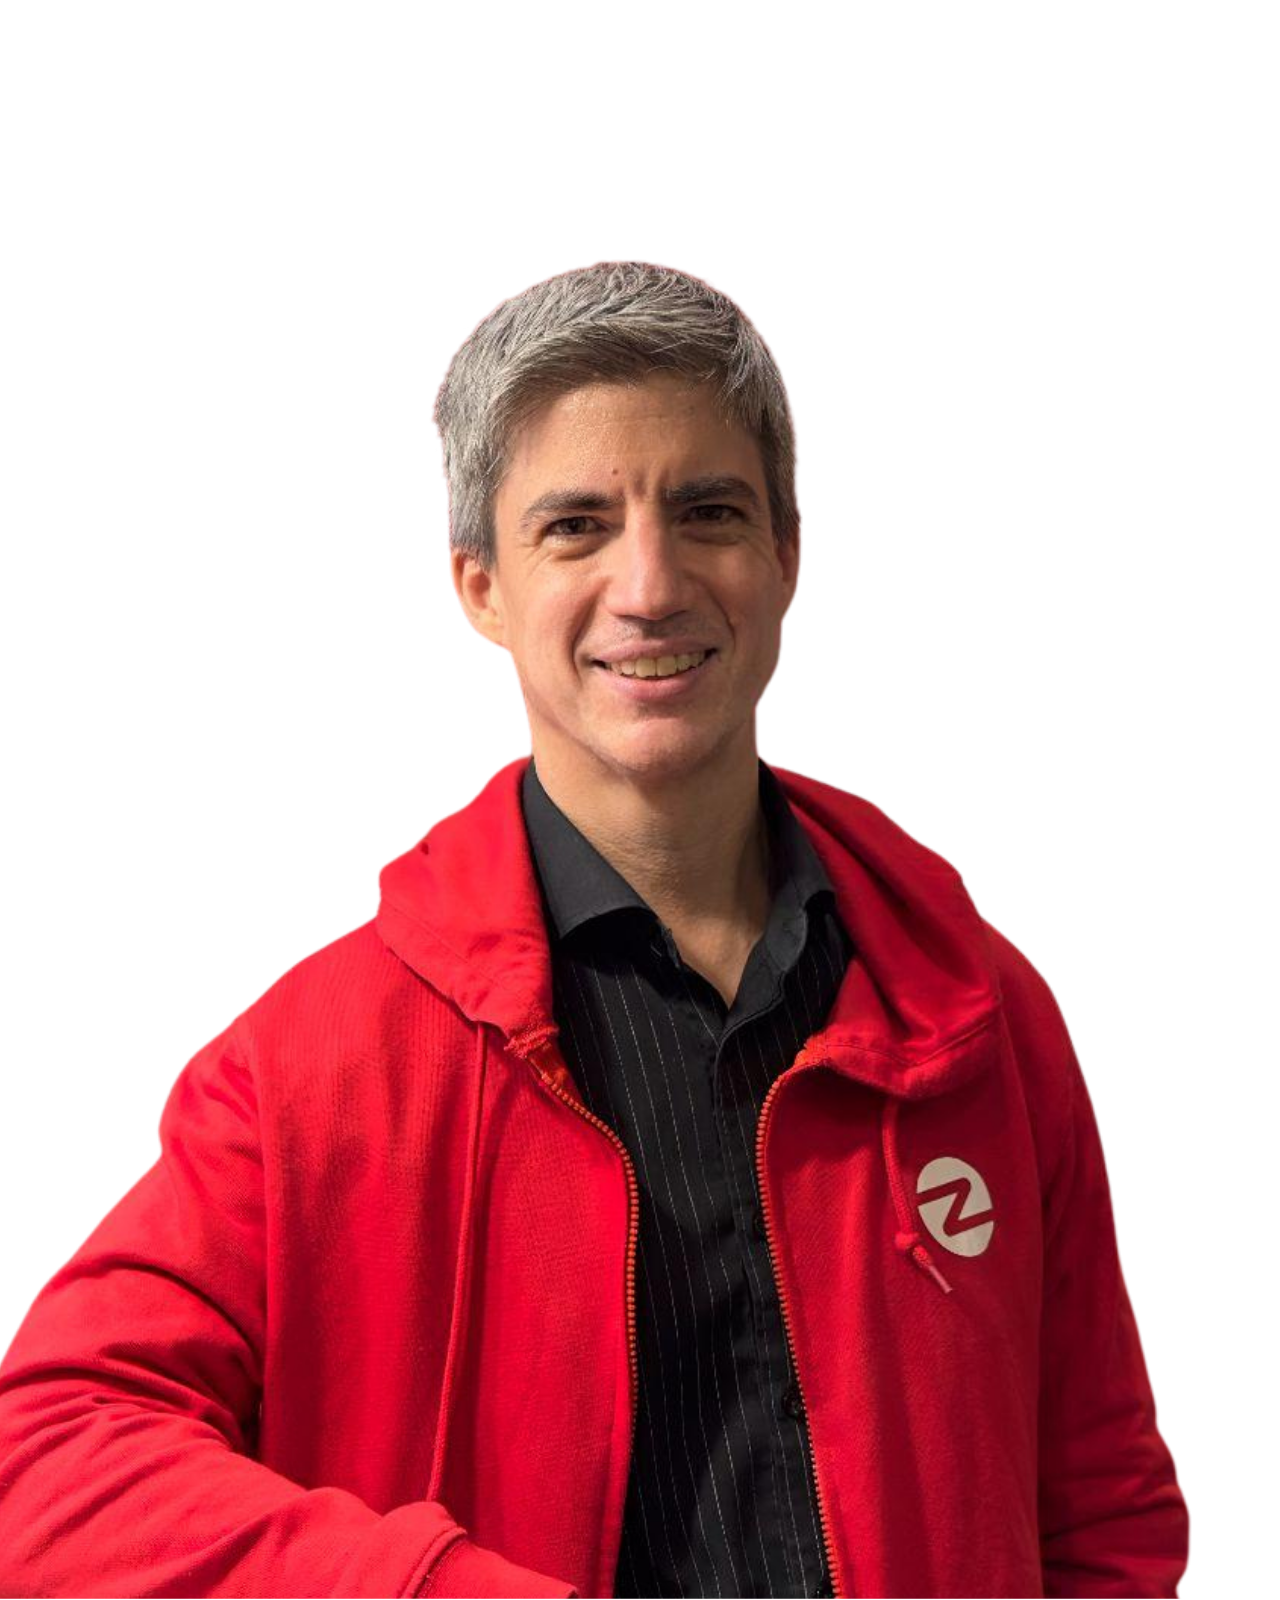
Michael is Head of Engineering with broad experience leading teams that build large-scale software systems and modern engineering platforms. He is especially interested in how data teams keep pipelines maintainable as they grow - applying the same structure, testing and review discipline to data code that software teams take for granted.
A short technical setup is required before the session. Detailed instructions will be sent to confirmed participants in advance - no preparation is needed at the point of registration. The hands-on labs run in a provided Databricks and Delta Lake environment.
| Participant | Standard Fee | Special Rate |
|---|---|---|
| Per participant (per pax) | $1,250 | $1,000 |